

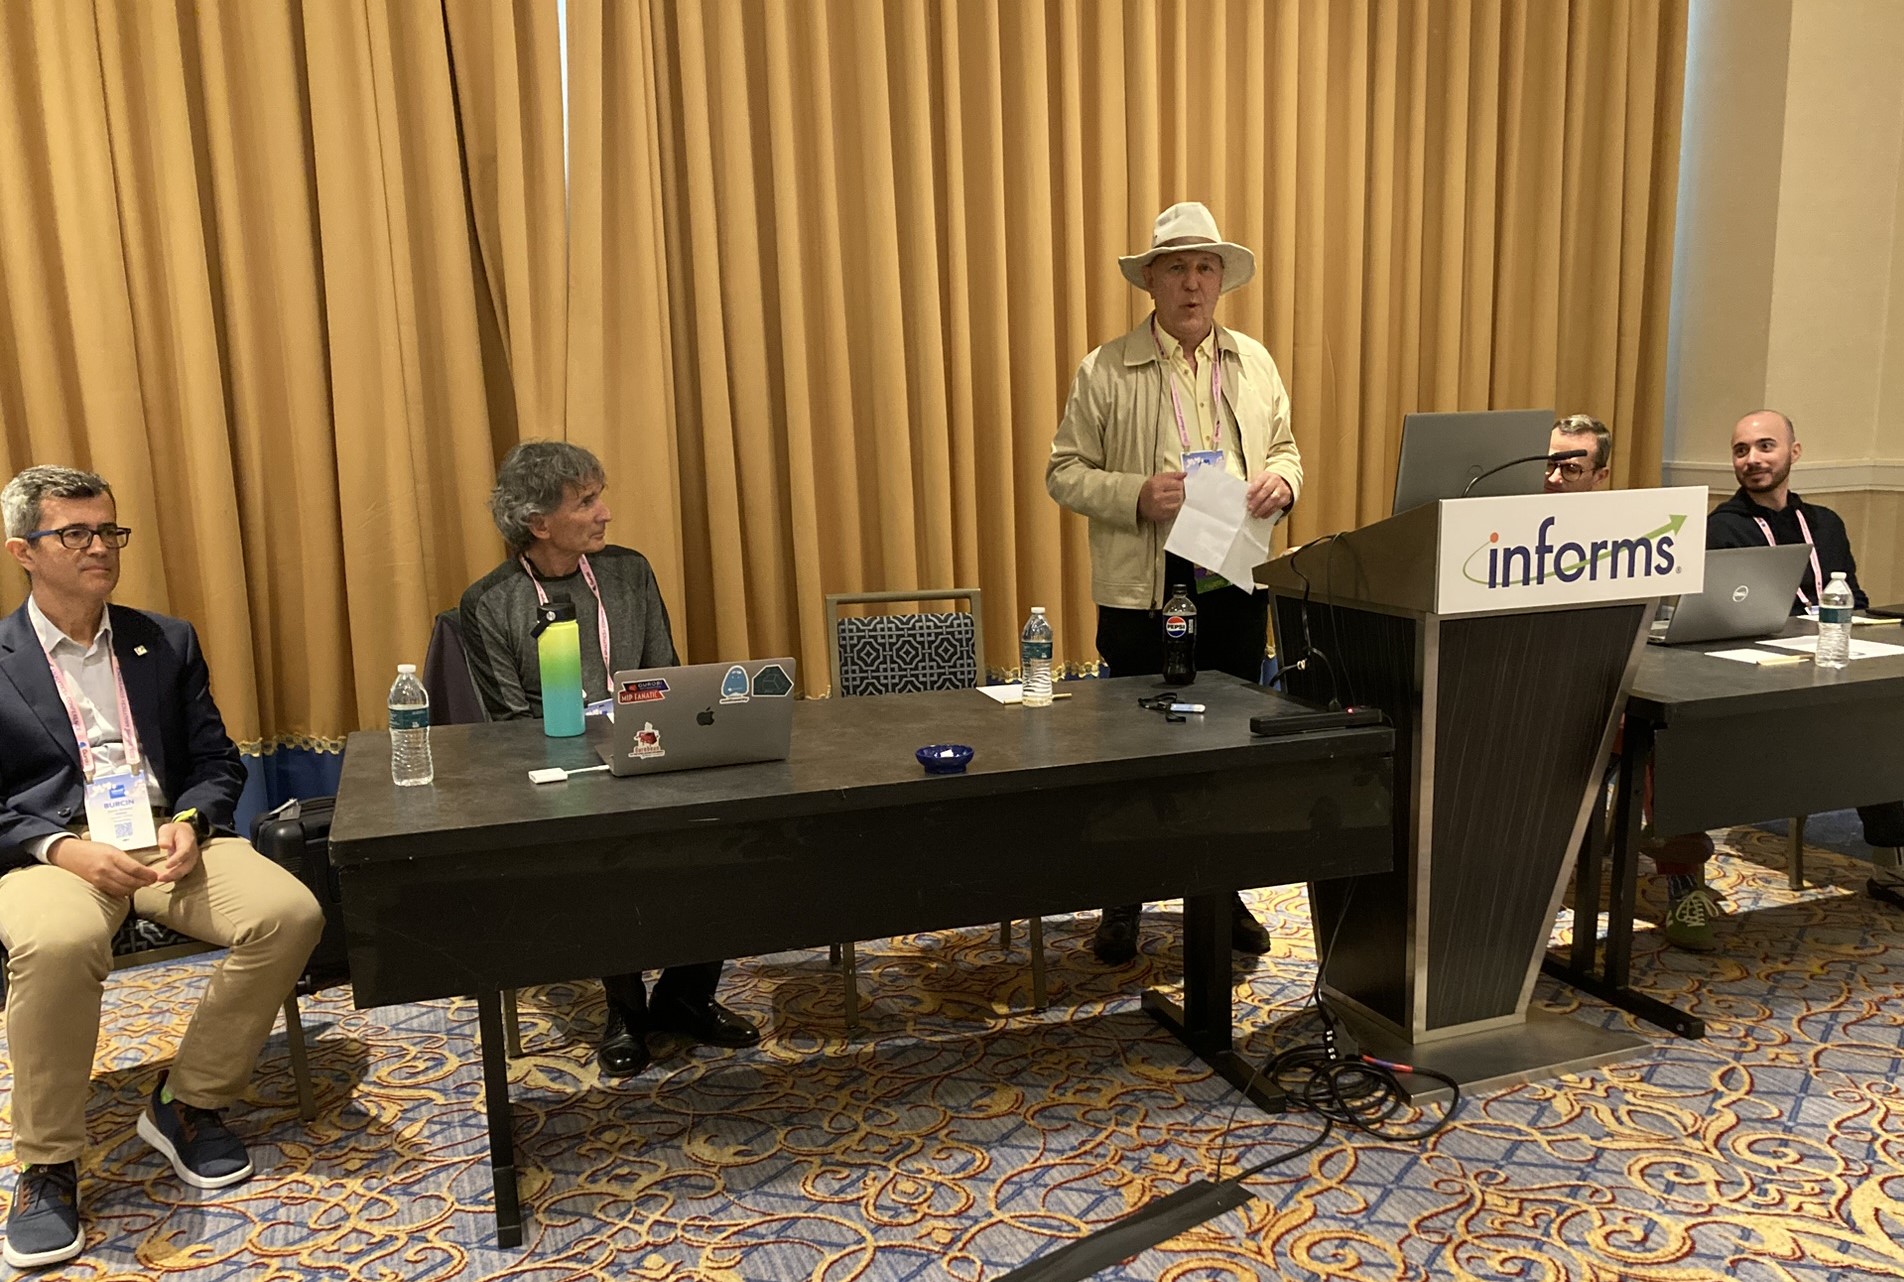
At the INFORMS Analytics+ Conference in April, I moderated a panel on GPUs, the Primal-Dual Hybrid Gradient (PDHG) and “the ongoing evolution of Mixed Integer Linear Programming (MILP) and an investigation into the potential value of each to solve larger and more complex models.” I was asked because of my research at Stanford University and Princeton University in the late 1980’s and early 1990’s, when I invented the primal-dual infeasible interior point method to solve complex optimization and linear programming problems.
The panelists were Burcin Bozkaya, Senior Developer Relations Manager at NVIDIA; Ed Klotz, Senior Mathematical Optimization Specialist at Gurobi; Imre Pólik, Director of Continuous and Global Optimization at FICO; and Alex Fender, Director of Decision Intelligence at NVIDIA. I will briefly summarize their presentations and then offer some comments.
What is a GPU?
Burcin began by challenging the audience to think differently about performance. Using the analogy of a bus versus a car, he explained that the answer to “which is faster?” depends on the task. A car may be faster for transporting a few people, while a bus is more efficient for moving hundreds. He described CPUs as optimized for low-latency sequential processing (therefore like a car) and GPUs as designed to process much larger amounts of data in parallel (like a bus).
Burcin then demonstrated how workload size influences processor performance. Using a simple cooling simulation, he compared execution times on a single-threaded CPU, a multi-threaded CPU, and a GPU. For small problems, the single-threaded CPU performed best. As the number of simulated objects increased, multi-threaded CPU execution became more efficient. At very large scales—hundreds of millions of independent calculations—the GPU achieved approximately a tenfold speedup by distributing the computation across thousands of parallel threads.
He followed with an overview of the GPU architecture, describing streaming multiprocessors, high memory bandwidth, SIMT (single instruction, multiple threads), and the low cost of thread switching compared with CPUs. He explained that GPUs organize computations into thousands of parallel threads and execute them across many streaming multiprocessors, allowing very large matrices and datasets to be processed efficiently. Burcin concluded by emphasizing that GPU performance depends on structuring computations so they can be divided into large numbers of parallel tasks and executed across the available hardware resources.
An Introduction to PDHG
Ed Klotz explained how the Primal-Dual Hybrid Gradient (PDHG) algorithm works and why it has become well suited for GPU computing. He showed how the primal and dual formulations of a linear program lead naturally to a saddle-point problem. He introduced a game-theoretic interpretation in which a primal player and a dual player iteratively improve their respective solutions, illustrating how primal feasibility, dual feasibility, and complementary slackness emerge through this process.
Ed then showed how adding regularization terms and simple update rules produces the PDHG algorithm. He walked through the primal and dual updates, including the projection step that maintains nonnegative primal variables, and demonstrated how the iterative exchange between the primal and dual solutions converges to an optimal primal-dual pair. Ed emphasized that PDHG reaches optimality through a fundamentally different computational process than either the simplex or barrier methods.
He concluded by discussing why PDHG maps effectively to GPU architectures. The algorithm relies primarily on large matrix-vector operations that can be executed in parallel across thousands of GPU cores while maintaining high processor utilization and a relatively small memory footprint. Ed also reviewed the current limitations of the approach, including slower convergence near optimality, lower solution accuracy than simplex or barrier methods in some cases, and challenges for crossover and sensitivity analysis. He noted that both the algorithms and GPU hardware continue to evolve rapidly, making PDHG an active area of research for solving increasingly large linear programming models.
GPU Implementations at FICO
Imre Pólik described FICO Xpress’s experience implementing GPU-based optimization algorithms and the lessons the development team learned while bringing the technology into production. He explained that Xpress has supported a hybrid gradient implementation for several years and recently added a GPU implementation, with an upcoming release incorporating a newer variant of the algorithm. Because the two variants exhibit different performance and robustness characteristics, FICO has implemented and maintained both versions on both CPUs and GPUs.
Imre reviewed the practical aspects of the implementation, including support for NVIDIA GPUs dating back to 2018, single-GPU execution, and the use of single-precision arithmetic on GPUs to reduce memory requirements while maintaining good numerical behavior. He reported consistent performance across a wide range of hardware, from laptop and gaming GPUs to high-end H100 systems, with average speedups of roughly eight times over a highly optimized CPU implementation for large linear programs. He also noted that GPU acceleration becomes increasingly beneficial as problem size grows, while traditional interior-point methods remain competitive for smaller models.
Imre also discussed implementation challenges, pointing out that achieving good performance required moving virtually the entire algorithm onto the GPU because transferring data between CPU and GPU proved too expensive. He also emphasized the architectural differences between CPU task parallelism and GPU data parallelism, arguing that future optimization software will require algorithms designed specifically for massively parallel hardware rather than adaptations of traditional simplex or interior-point methods. He concluded that continued progress will depend as much on developing new optimization algorithms as on advances in GPU hardware.
GPU Accelerations and cuOpt Advances
Alex Fender described NVIDIA’s strategy for accelerating optimization by moving the entire optimization workflow onto GPUs rather than accelerating only selected computational kernels. He explained that NVIDIA’s goal is to build a complete GPU-native software stack—including data processing, mathematical libraries, machine learning, and optimization—so that optimization models can remain on the GPU throughout execution. This philosophy led to the development of the open-source cuOpt library and NVIDIA’s investment in GPU implementations of PDHG, barrier methods, and mixed-integer optimization.
Alex reviewed several of the recent advances in cuOpt. He described NVIDIA’s concurrent optimization framework, which allows CPU and GPU solvers—and even multiple GPU solvers—to run simultaneously. He also discussed optimizations to sparse matrix-vector operations, GPU implementations of barrier methods built around high-performance Cholesky factorization, and continued work on deterministic GPU algorithms that can be executed alongside PDHG. He noted that recent improvements have been driven not only by NVIDIA’s engineering efforts but also by advances emerging from the academic research community.
Alex discussed NVIDIA’s work on GPU-accelerated mixed-integer programming. Alex described GPU implementations of primal heuristics, root-node processing, branch-and-bound components, and support for quadratic and second-order cone programming. He presented benchmark results showing strong progress in finding high-quality feasible solutions quickly, while noting that improving proofs of optimality remains an active area of development. Looking ahead, he suggested that future optimization systems are likely to combine increasingly capable GPUs with tightly integrated CPUs, while continuing to leverage open-source software and AI agents to make optimization models easier to develop and deploy.
Experiences with GPU at Gurobi
Ed Klotz then presented Gurobi’s current perspective on PDHG and GPU acceleration. He described how users can enable PDHG in the latest version of Gurobi, either for standalone linear programs or for the root relaxation of mixed-integer programs, and outlined the current requirements for running the GPU implementation. He also offered practical guidance on when users should consider PDHG, including very large linear programs, difficult root relaxations, and applications where a primal-dual solution is sufficient or where crossover can be applied to obtain a basic solution.
Ed reviewed Gurobi’s evaluation of solution quality, emphasizing the role of crossover in reducing constraint violations and improving the accuracy of PDHG solutions. He presented benchmark results comparing CPU and GPU implementations and discussed how GPU memory bandwidth creates the potential for substantial performance gains on large-scale linear programs. He ended by noting that both GPU hardware and first-order optimization algorithms are advancing rapidly and that PDHG already provides a promising approach for solving extremely large LPs, while GPU acceleration for mixed-integer programming continues to evolve through targeted acceleration of individual solver components.
Commentary
This panel brought back memories of my work that led to primal-dual infeasible interior point algorithms that are at the core of all the implementations today.
We’re in the early stages of GPU acceleration and everyone is trying to see where it fits. The two main obstacles I see are accuracy of solution and application to real-world problems that are almost always MIPs. Today the GPU-based solvers are faster on certain really large linear programming problems, but there is work to do to make them robust, e.g., on infeasible/unbounded problems. There are still issues with the accuracy of the solutions with respect to tolerances. There is active research on how to tune the algorithms. There is work to do to make it applicable to MIP. Again, this reminds me of where things were in the late 1980’s with respect to interior point algorithms needing more research to achieve that level of trust and reliability.
During the Q&A at the end of the panel, I noted that when I make recommendations to clients about solvers on how to solve a problem, I consider cost. Before you use GPUs in the cloud or use your own GPU hardware, you should conduct a cost analysis to understand what you will be paying for extra compute cycles, etc. Alex Fender at NVIDIA replied that there are hundreds of millions of GPUs out there and available, so try them if possible. He said every Fortune 500 company has one and it may take a little bit of navigating at your company to find them, but it is worth the effort.
In my experience at Princeton Consultants over the past 12 years, I’ve not seen the need to solve extremely large linear programs. Having said that, as this technology matures, we may have opportunities to formulate much larger problems and see how well we can solve them. We will be watching the evolution of these methods and technology with a keen eye.
To discuss this topic with Irv, contact us to set up a call.