


At the INFORMS Analytics+ Conference in Indianapolis, Irv presented a workshop along with Siddhesh Pore of Databricks, https://www.databricks.com/. They discussed data-first principles and best practices, data prep and engineering, and optimization integrations on the Databricks platform. Following is an edited excerpt from the Q&A at the end of the program.
Audience Member: I enjoyed the presentations about the real‑world applications and the real-world warehouse. Where do you see today and in the future the balance between raw data, which is often extremely ugly, and tidy data? You showed a spectrum including business‑oriented data, which is probably more curated than what Operations Research analysts are used to, and raw data.
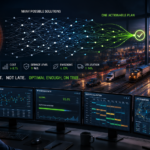
Irv: To give you an idea of what we tend to see, consider this diagram representing the gamut of the work that we do at Princeton. The central large arrow is based on the INFORMS Analytics Framework, the former Job Task Analysis that serves as the basis of the INFORMS Certified Analytics Practitioner exam.

Starting at the left with business problem framing, we ask clients, “What are the decisions that you are making? What data is going to inform those decisions?” Sometimes the data exists; sometimes it is in people’s heads; sometimes it has to be collected as part of the user interface. For the data that exists out in systems, we often have to pull it and make transformations. For example, you might get production cost and inventory cost data, but need the sum as input to a model. We often do those kinds of transformations to set up for optimization.
We like to talk about “raw data” and “model data.” In our methodology (see https://princetonoptimization.com/blog/optimization-engagements-throughout-the-solution-development-lifecycle/), we start by understanding the problem before we write the math model. We say, “Given this data, we know we want these kinds of outputs. Now, what do we need to do? Let’s write a document that defines the raw data. Then, let’s write a document that is the model data and the transformations required.” We can give that work to a consultant-practitioner who knows nothing about optimization. Once we have model data, we often can bang out a model and get it working pretty quickly, compared to all the work with the data.
Regarding the transformations of data, consider cases where you need to generate a demand forecast that becomes input to an optimization model. If you are talking about dealing with Big Data, that may be the older, former way we talked about it—you’ve got to do all this work and create a forecast that creates 20 numbers to feed into an optimization model. In past conversations with Databricks executives, I said that in the optimization world we tend to work with Little Data. We don’t often work with Big Data, which is what the Databricks platform is meant for.
Often, we have to take Big Data and transform it for optimization. This is where the Databricks platform really shines, and we look at it as a way of managing projects—more than just something to pull different tools together and handle transformations and analyses.
When we illustrate the benefits of optimization, you often need to transform the optimization solution to enable a post analysis. On the output side, an optimization model is producing data representing decisions. You have to analyze that data and use good visuals and charts like the ones that are available in the Databricks platform. Having a unified place where you can handle input and output is compelling. The integration in Databricks for optimization is relatively new. Optimization practitioners and data engineers and scientists have been living in separate worlds, which at Princeton we are trying to overcome by, for example, helping tie together Gurobi and pandas, https://www.gurobi.com/resources/faq/gurobipy. The integration in Databricks is new and it also gets optimization practitioners to think differently because, as I was saying, we come from training in a world where we thought model-first. Now, when we start thinking data-first, we think about the tools needed to be data-first and to build optimization‑based solutions.
At Princeton we view the work by Databricks in integrating Gurobi, https://www.gurobi.com/, as moving forward in the data-first way of thinking. We are looking forward to more collaboration with Databricks so we can bring our best practices for optimization into the Databricks world, and Databricks can bring their best practices for working with data into our world.
Contact us to discuss this topic with Irv.